Open source · Apache 2.0 · runs on your machine
Run ML experiments overnight. Keep only what's proven.
Claude proposes ideas. ResearchForge tests every one against a frozen baseline, rejects what fails, and shows you exactly why the winner won — on a Kaggle competition or your own repository.
$ /overnight https://www.kaggle.com/competitions/enveda-CASMI26-…compute Kaggle GPU — competition data stays on Kagglepool 54 ideas · public kernels, arXiv, your notes▶ hyp-003 leader-safe RRF reorder of candidateslocal MRR@25 0.8999 → 0.9032 · public LB 0.156 → 0.158 ✓ kept▶ hyp-005 confidence-gated fallback interleavinglocal 0.9032 → 0.9000 · public LB 0.158 → 0.160 ✓ kept (LB beats CV)▶ hyp-007 pure fallback for ranks 2–25local 0.8999 → 0.8649 · public LB 0.166 → 0.164 ✗ rejected, reason kept☀ morning briefing pushed to your phone (ntfy)
$ researchforge results showARC-AGI-3 · baseline frozen · 4 levels (offline, 25 games)✓ exp-011 model upgrade Qwen3.6 → Qwen3.8public 1.21 → 1.55✓ exp-012 LoRA fine-tune on 9 of its own wins validatedpublic 1.55 → 1.94 (+25%)✗ exp-007 executable world model + planningoffline 5 vs 4, public 0.58 vs 1.21 — proxy failed✗ exp-014 fine-tune data 9 → 22 gamespublic 1.20 vs 1.94 — more data hurt14 experiments · 10 rejected with reasons · 1 validated
Works from Claude Code, Cursor, an Anthropic / Gemini / OpenAI key, or a local Ollama model · watch the demo
Real runs, in the open
Public Kaggle leaderboard · 15 Nov 2026
From a first score of 0.08 to 32.51. The record shows what really moved it — and the 10 ideas that did not.
A byte-identical resubmission scored 0.12, then 0.17 — so no single leaderboard number is trusted.
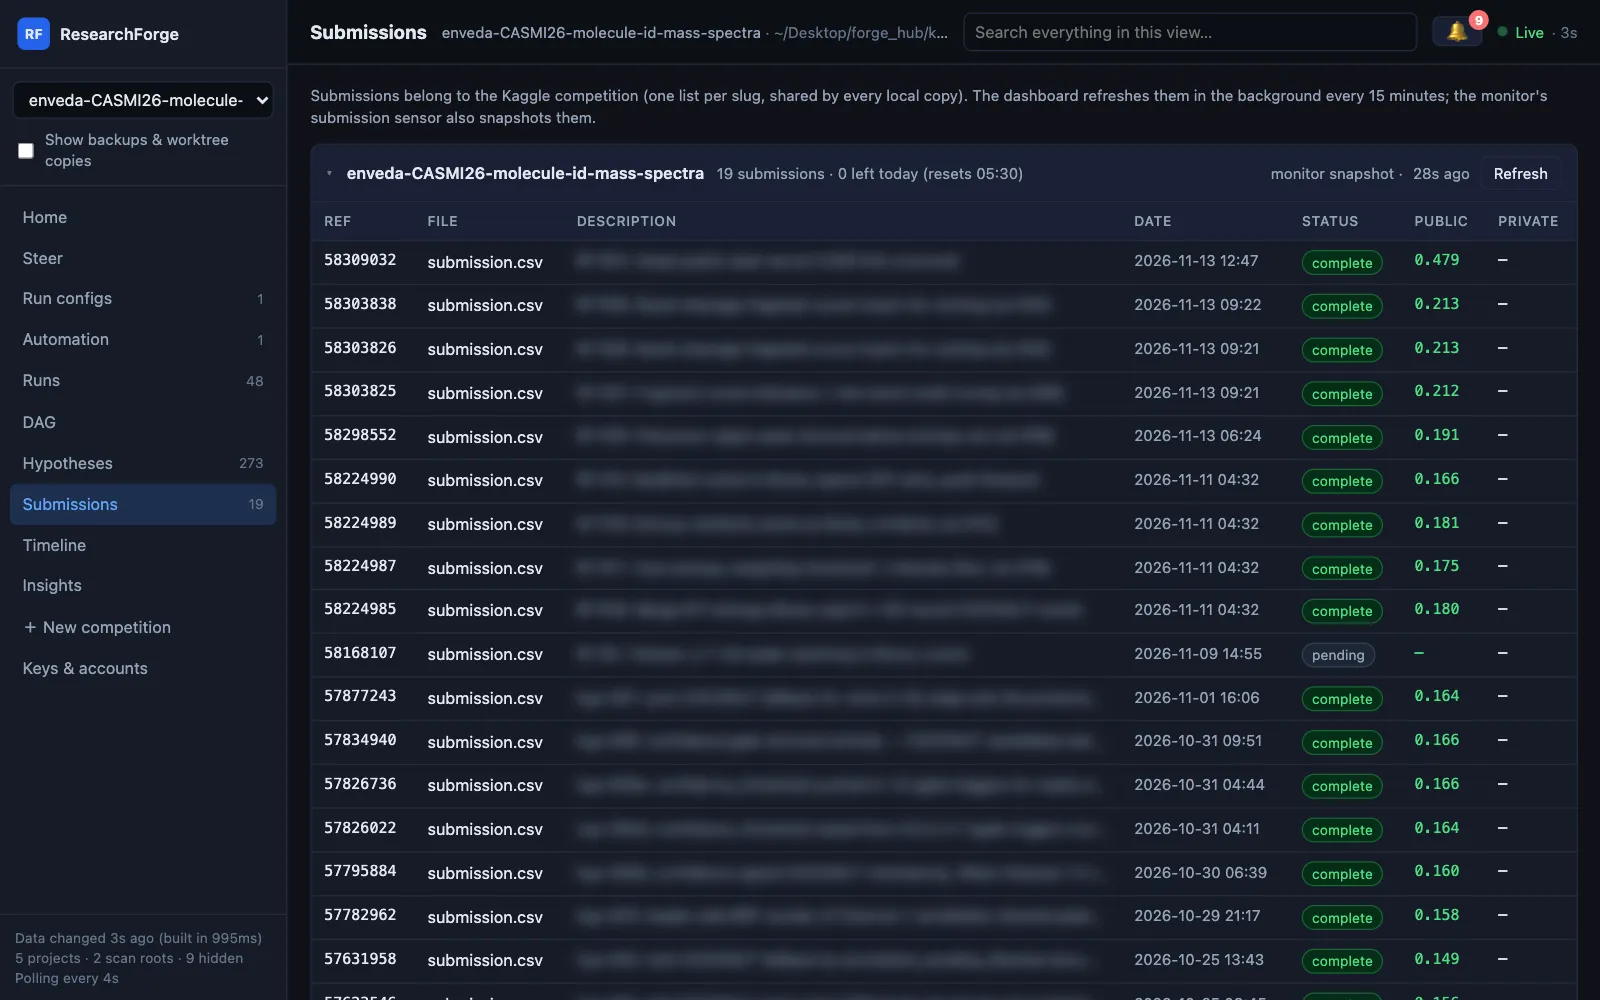
From rank 3,856 (5 Nov) to 1,421 (15 Nov). Our own rounds took the public score from 0.166 to 0.213; adopting a stronger public pipeline took it to 0.479.
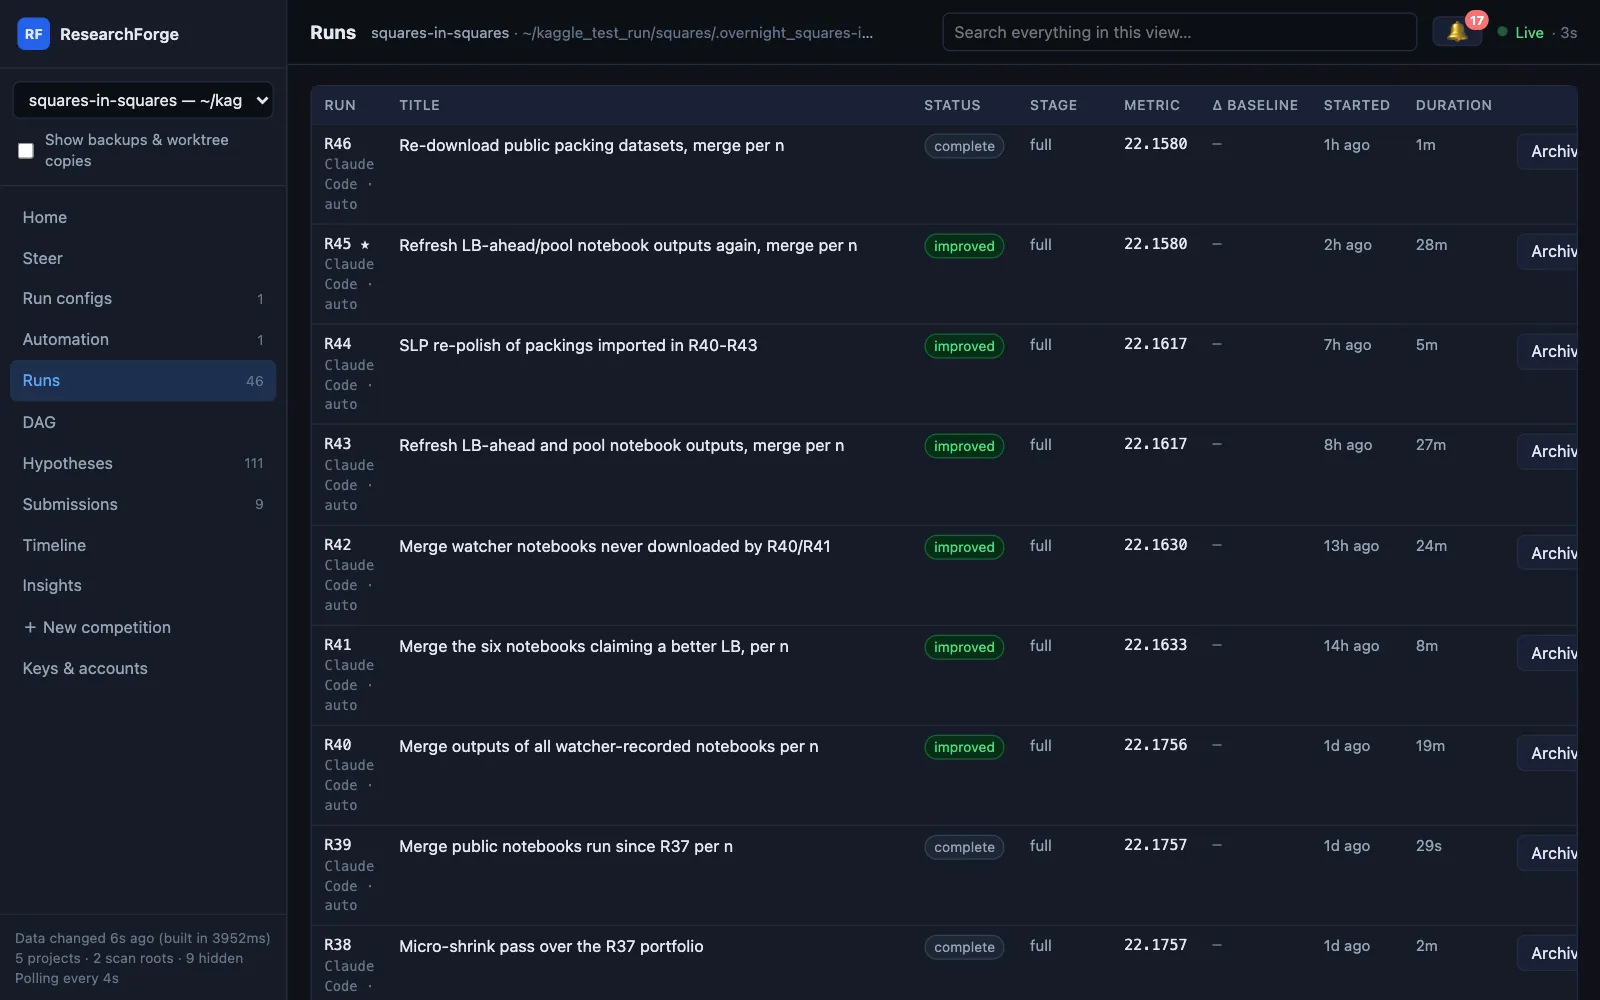
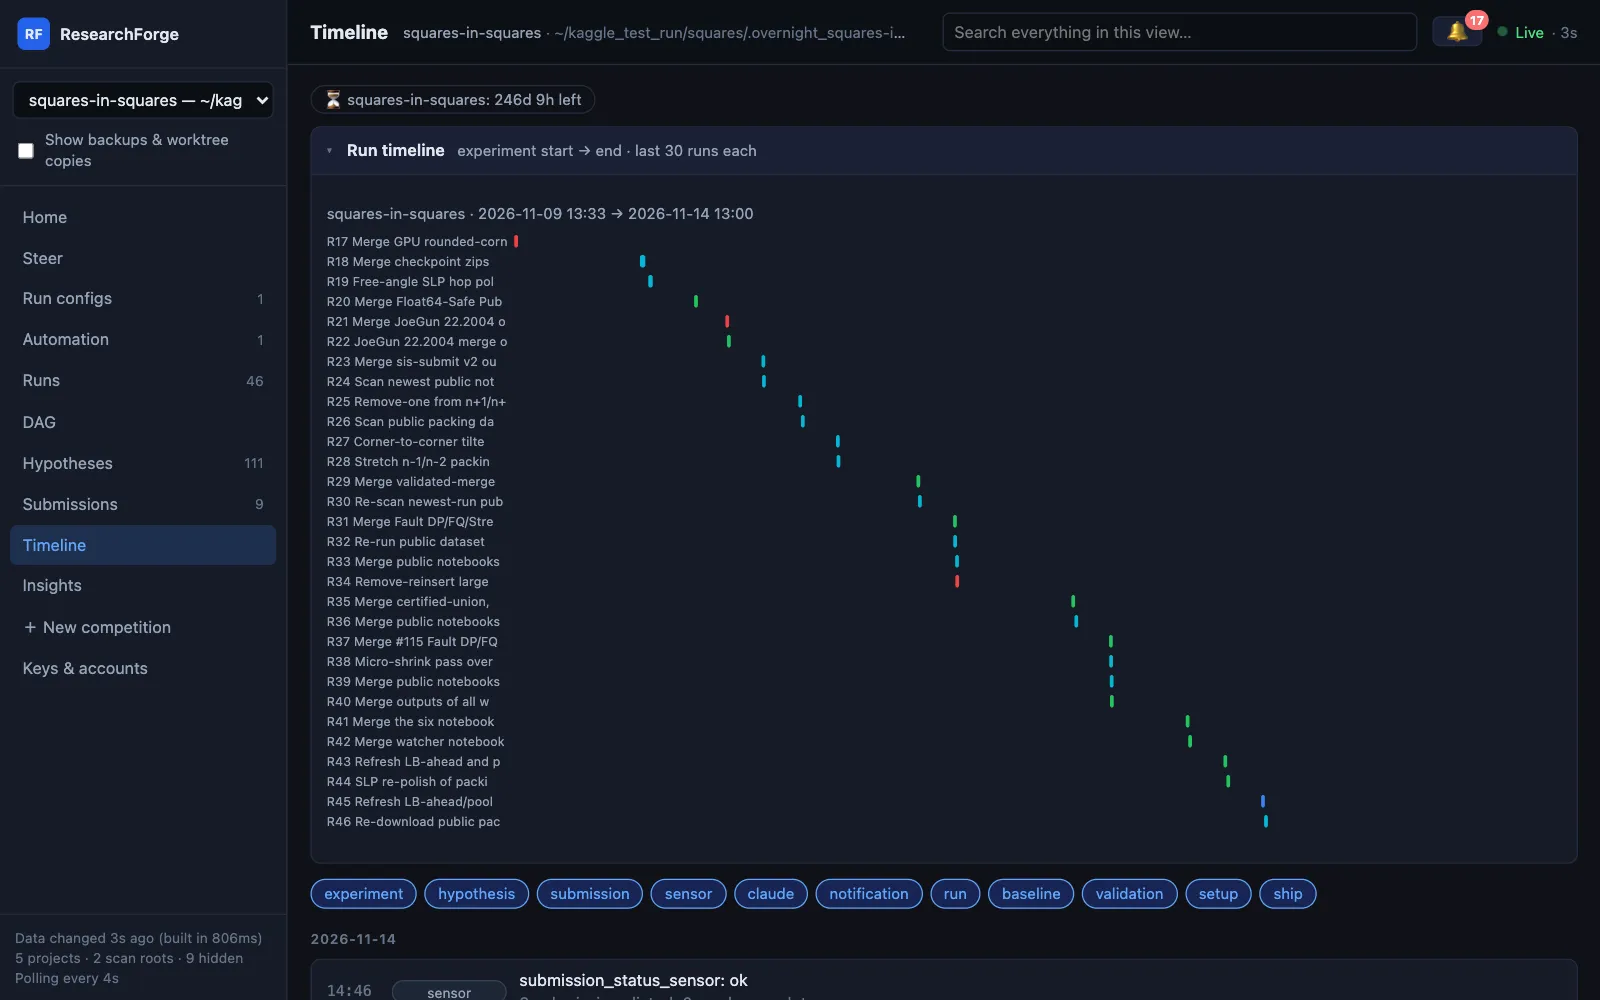
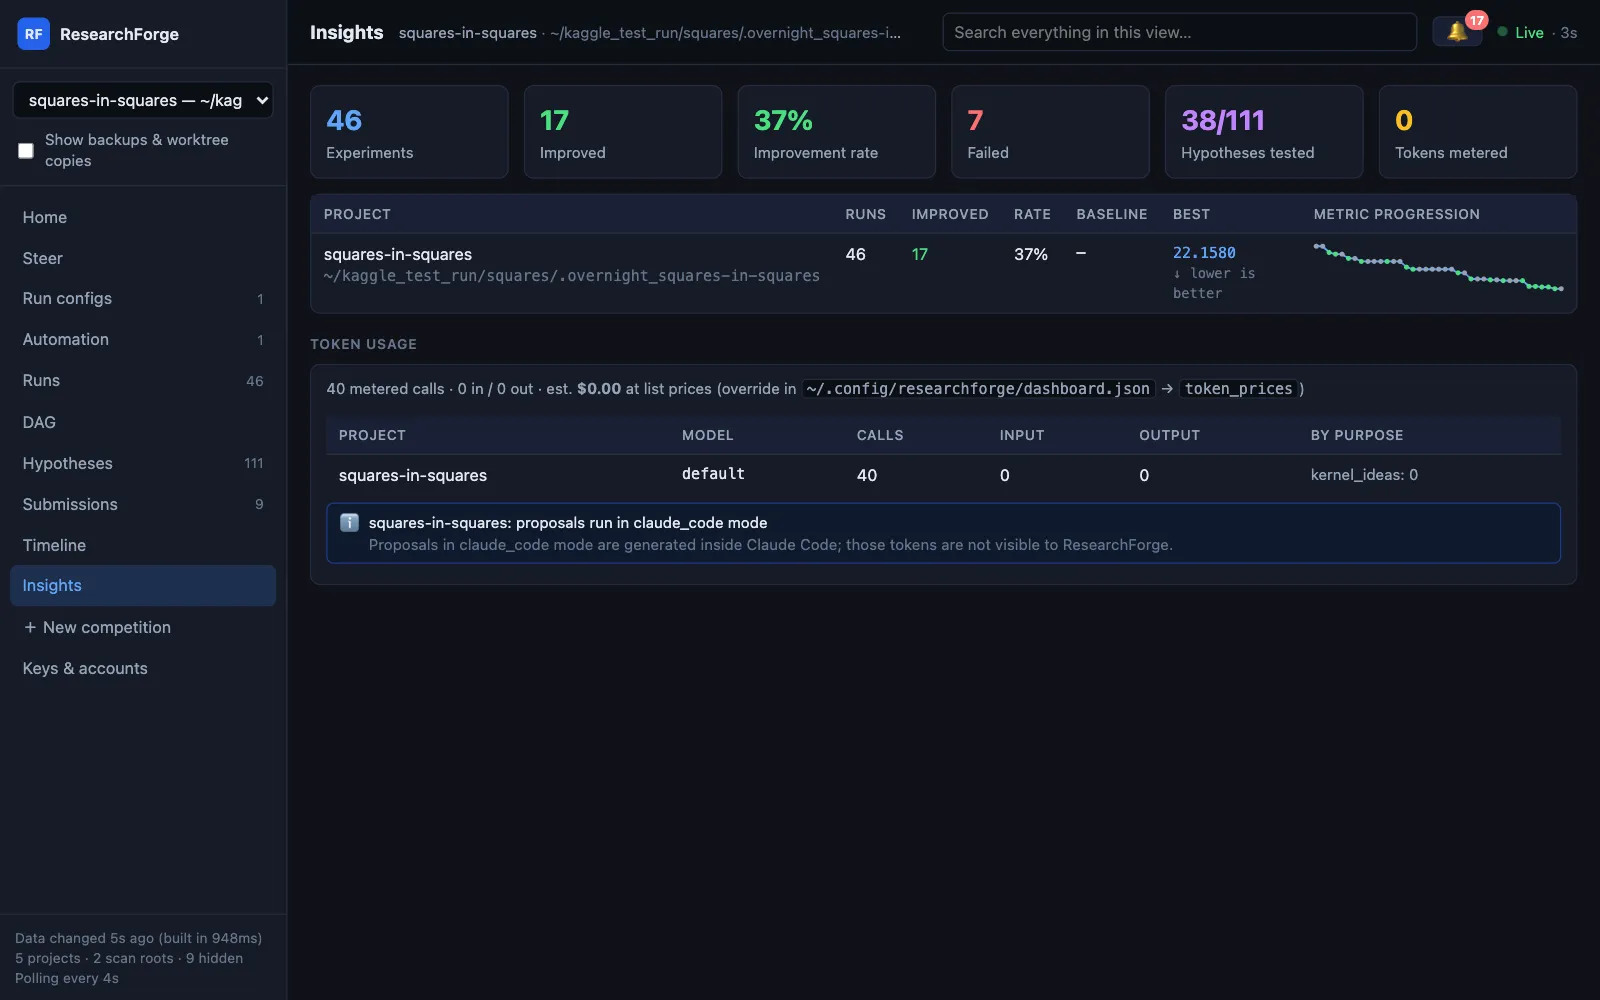
Public score from 22.2502 to 22.1756 in eight days, over 46 rounds. Almost every gain came from certified merges of public packings; our own search ideas have barely moved it yet.
Autoresearch, with a record
The autoresearch loop, for live Kaggle competitions and real repositories.
Karpathy's autoresearch showed the idea: let an AI agent change the code, run the experiment, keep the change only if the metric improves, and repeat all night. ResearchForge is an open-source, autoresearch-style AI research agent loop that takes that idea past a single training script.
Any metric, any repo, any Kaggle competition
Not one train.py: a contract fixes the metric, its direction and hard limits, and the baseline is frozen before anything runs.
Every experiment isolated and kept on record
Each idea runs in its own git worktree or on the GPU you pick — Kaggle, Colab, SSH or cloud — and every rejected idea stays with its reason.
Runs overnight, asks before it acts
Auto-run keeps experimenting with no chat open, questions reach your phone, and a Kaggle submission is always your click.
The problem
AI made generating changes cheap. Proving them is still expensive.
A coding agent can propose twenty plausible improvements before lunch. Without a fixed baseline, isolated runs and a record of what failed, “it got better” is easy to claim and hard to trust.
Too many plausible ideas
More hypotheses get generated than anyone has time to test properly.
No stable comparison
Baselines drift, dependencies change, and “improvement” becomes guesswork.
Failures disappear
Rejected ideas and their reasons get lost, so the same dead ends get retried.
Kaggle Overnight
Keep your Kaggle score current. Then push it further overnight.
Give it a competition URL. Every hour it checks the public notebooks and brings the best of them into your rounds, so your leaderboard score keeps pace with the field. Then auto-run runs improvement loops on top while you sleep, and the morning report reaches your phone.
- 01Competition URL/overnight <url> in Claude Code
- 02Keeps upthe best public notebooks, checked hourly, run as your rounds
- 03Pushes furtherauto-run improvement loops: run → measure → keep or reject
- 04Morning reportbetter submissions to approve, what failed and why
Picks the right GPU
Reads data size, competition type, your Kaggle GPU quota and local CUDA / Apple MPS, then recommends one target with a reason.
Runs where data may go
Kaggle GPU, this machine, Google Colab, your SSH server, or a RunPod or Lambda GPU — and refuses any target the data policy forbids.
Works while you sleep
Start at 23:00, send the briefing at 07:00. A background service keeps sensors watching new kernels, submissions and arXiv with your editor closed.
Runs ideas with no chat open
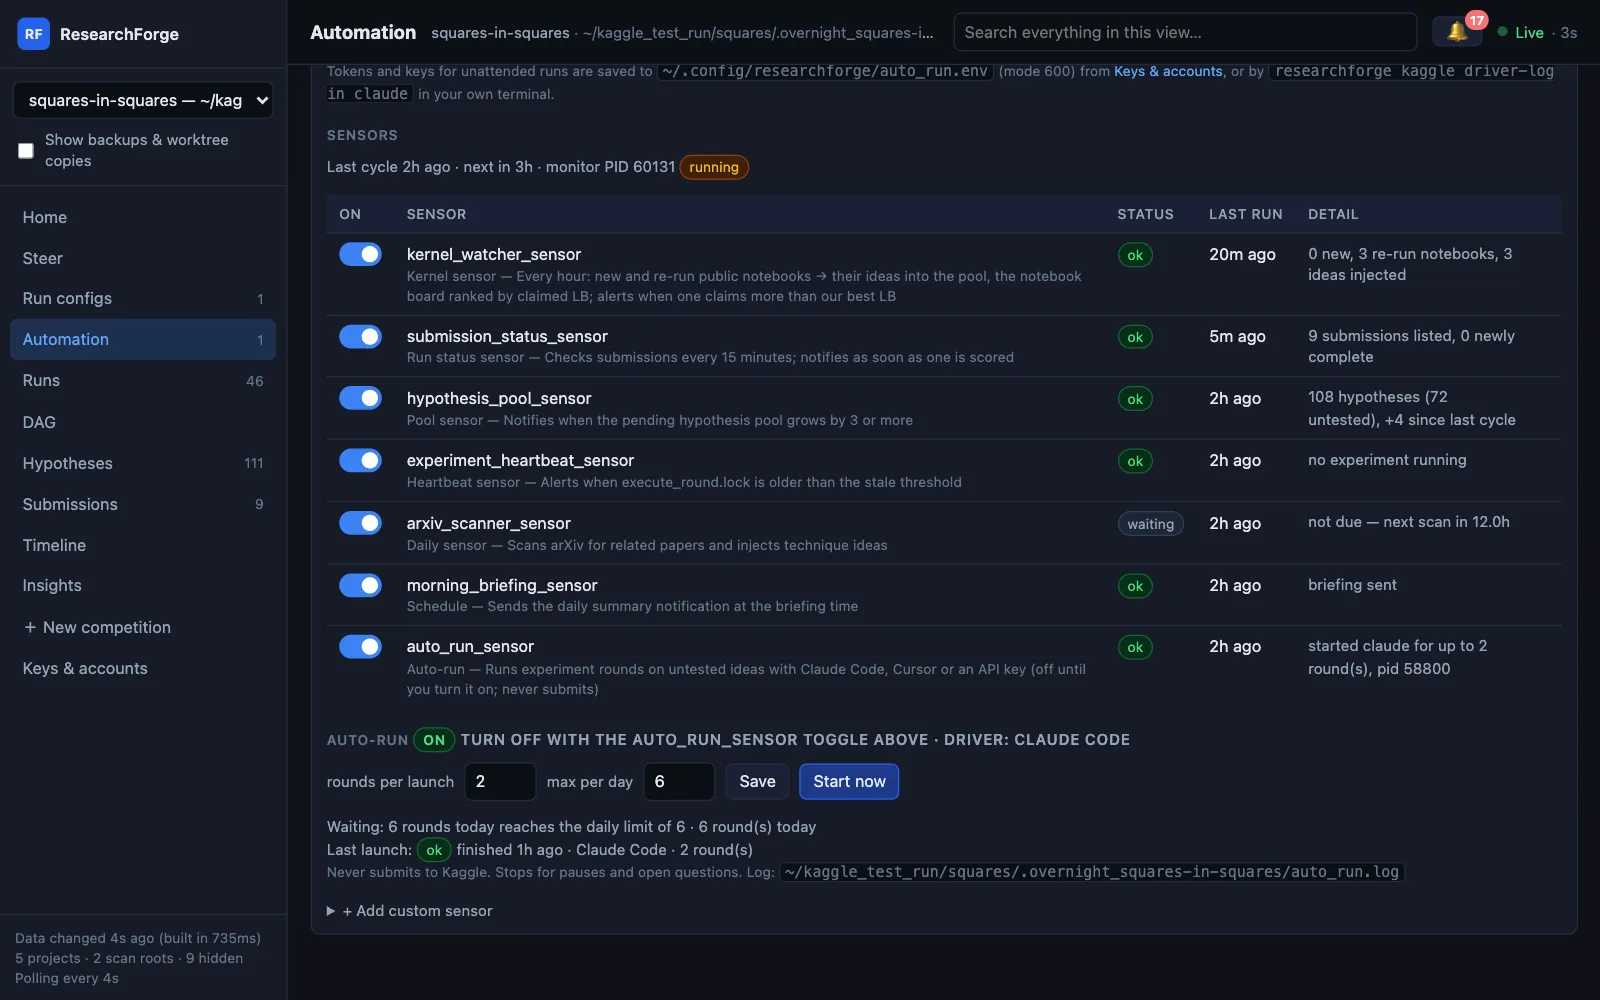
Opt-in auto-run starts rounds on untested ideas with headless Claude Code, the Cursor agent or your API key — within a daily limit, never submitting.
Remembers every failure
Winners become parents, independent wins get merged, and failed ideas stay on record with the reason so they are not tried twice.
Asks you on your phone
Results, a better public kernel and the morning report arrive by ntfy or Telegram. When it needs a decision it asks, and only the ideas in question wait.
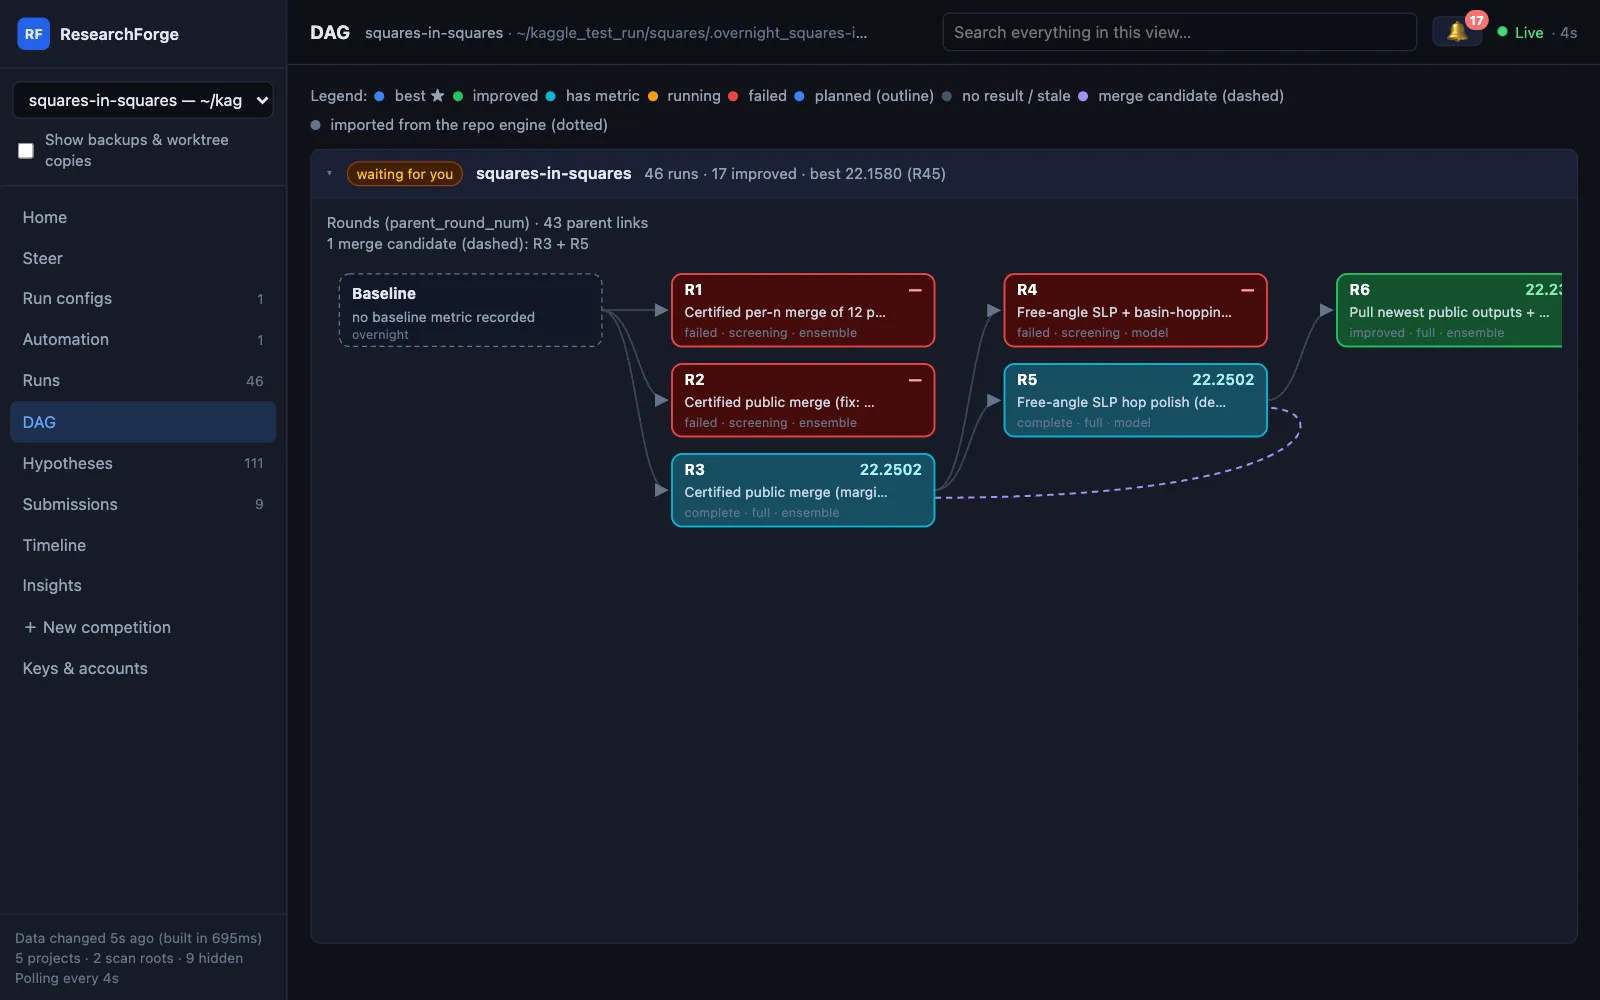
Research + experiment loop
From a research question or a repo metric to a validated result.
Point it at an idea or at a repository with a metric. Wake up to tested hypotheses, a validated winner shipped as a clean branch, and a record of every failure.
Explore a research idea
papers → landscape → hypotheses → cited report
$ /researchforge-startImprove a repository
frozen baseline → autorun → validate → ship a PR
$ researchforge autorun --max-hours 8Papers → hypotheses
Available nowarXiv search, a research landscape and testable hypotheses, each linked to its evidence.
Frozen baseline
Available nowMeasured before any change runs — optionally the mean of N runs — so every number is comparable.
Isolated git worktrees
Available nowEvery experiment runs from the same baseline commit. Your working branch is never touched.
autorun, unattended
Available nowAn experiment graph searched round after round, with stall, target and time limits.
Repeated validation
Available nowFinalists are re-run; a winner whose repeats spread too wide is refused.
Measured cost
Available nowCompute and token spend per project — measured, never estimated, unknown prices named.
Why the results can be trusted
Every experiment. Every failure. Every reason why.
ResearchForge doesn't just keep the winner — it keeps the path that proved it won. On ARC-AGI-3, ten of fourteen experiments were rejected, each with a measured reason.
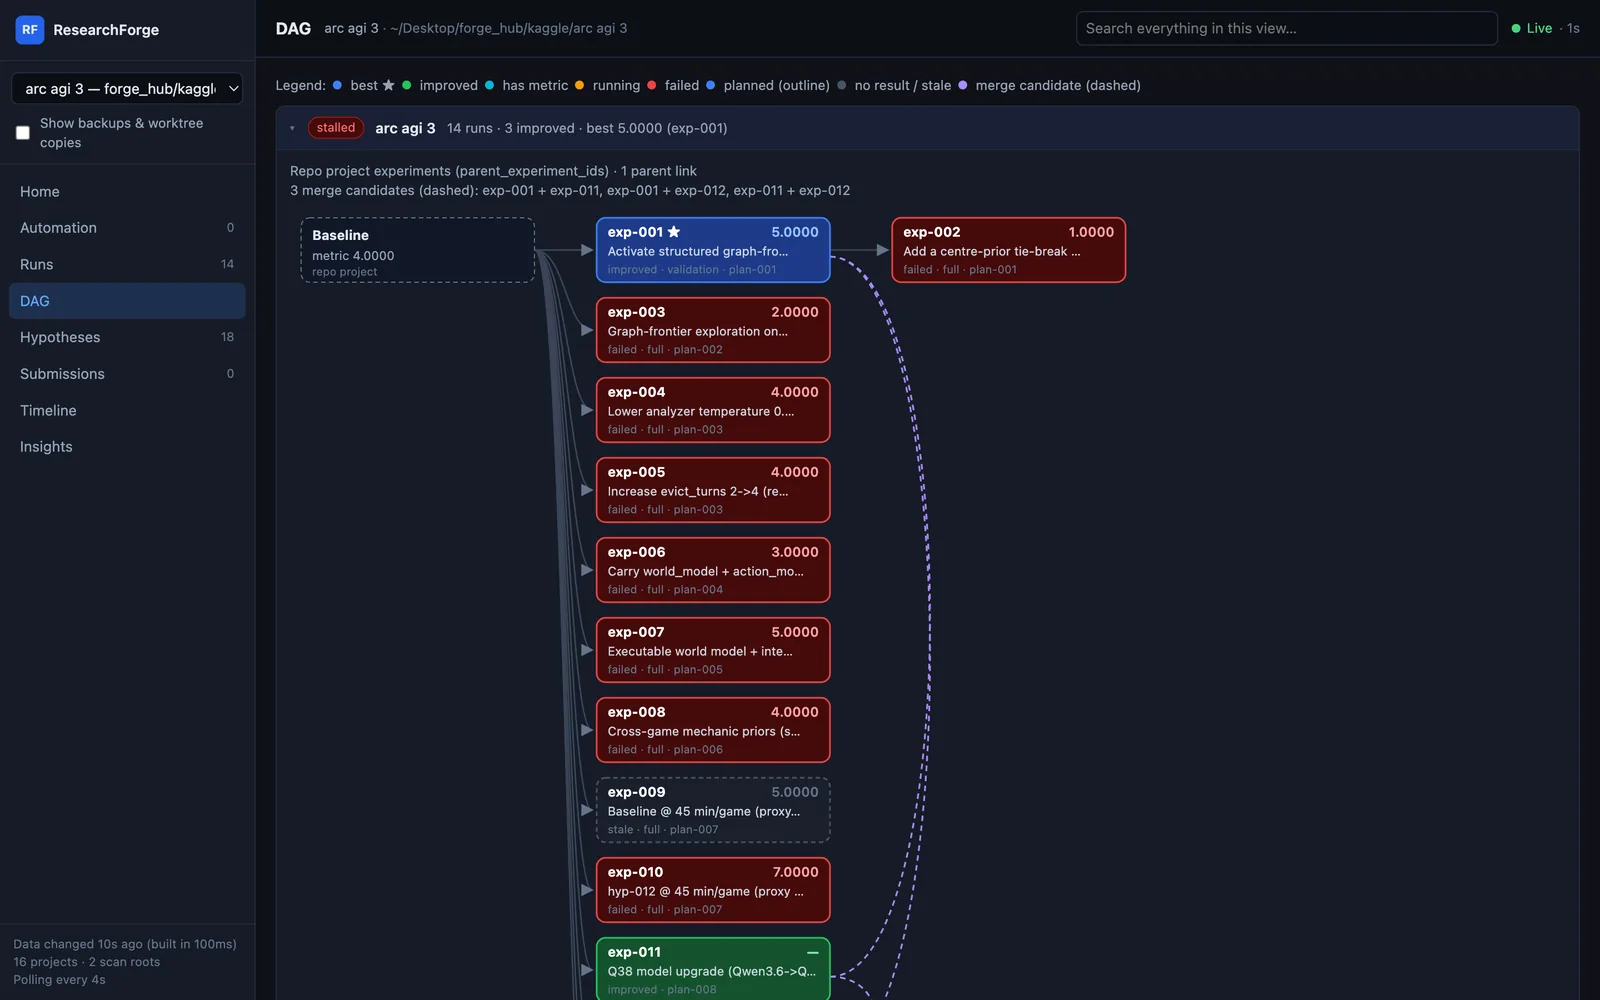
Better offline (5 vs 4 levels), 0.58 vs 1.21 on the leaderboard
Positive offline, 1.35 vs 1.94 on the leaderboard
1.20 vs 1.94 — naive scaling hurt
1.55 → 1.94 on the leaderboard — validated
Each experiment runs in its own git worktree from the same baseline commit. Your branch stays untouched; only a validated change ships, as a clean branch.
Runs while you sleep
It keeps experimenting. It asks before it acts.
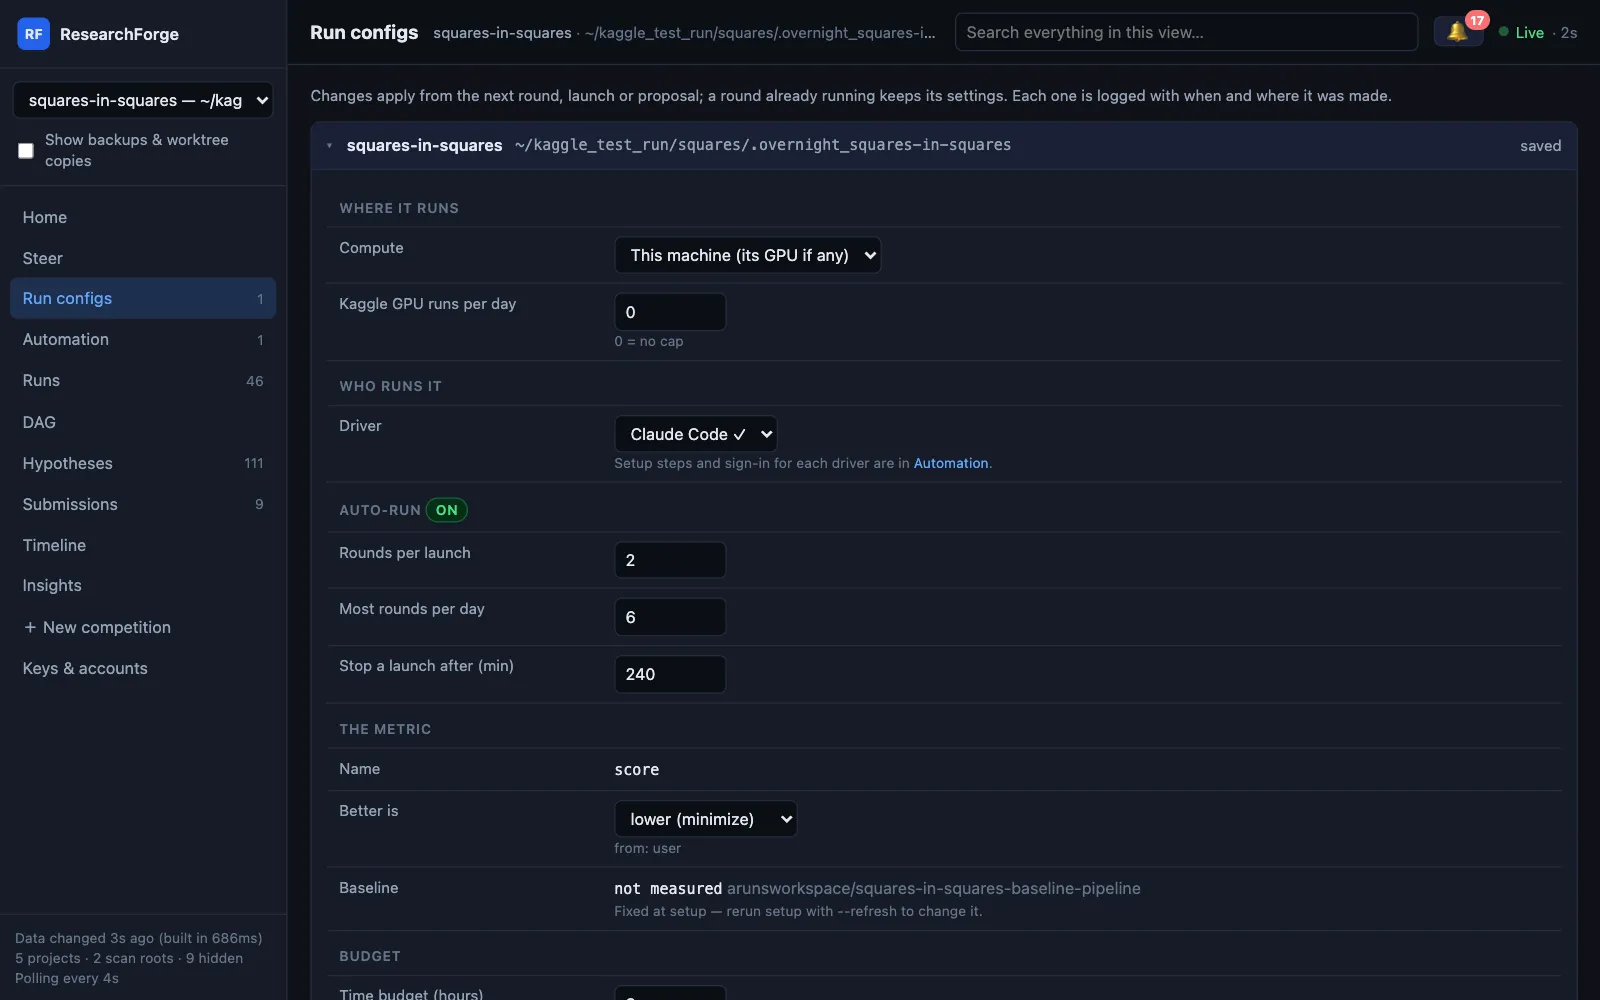
Auto-run starts rounds with no chat open. Decisions come to your phone and the dashboard's 🔔, and submitting is always your click.
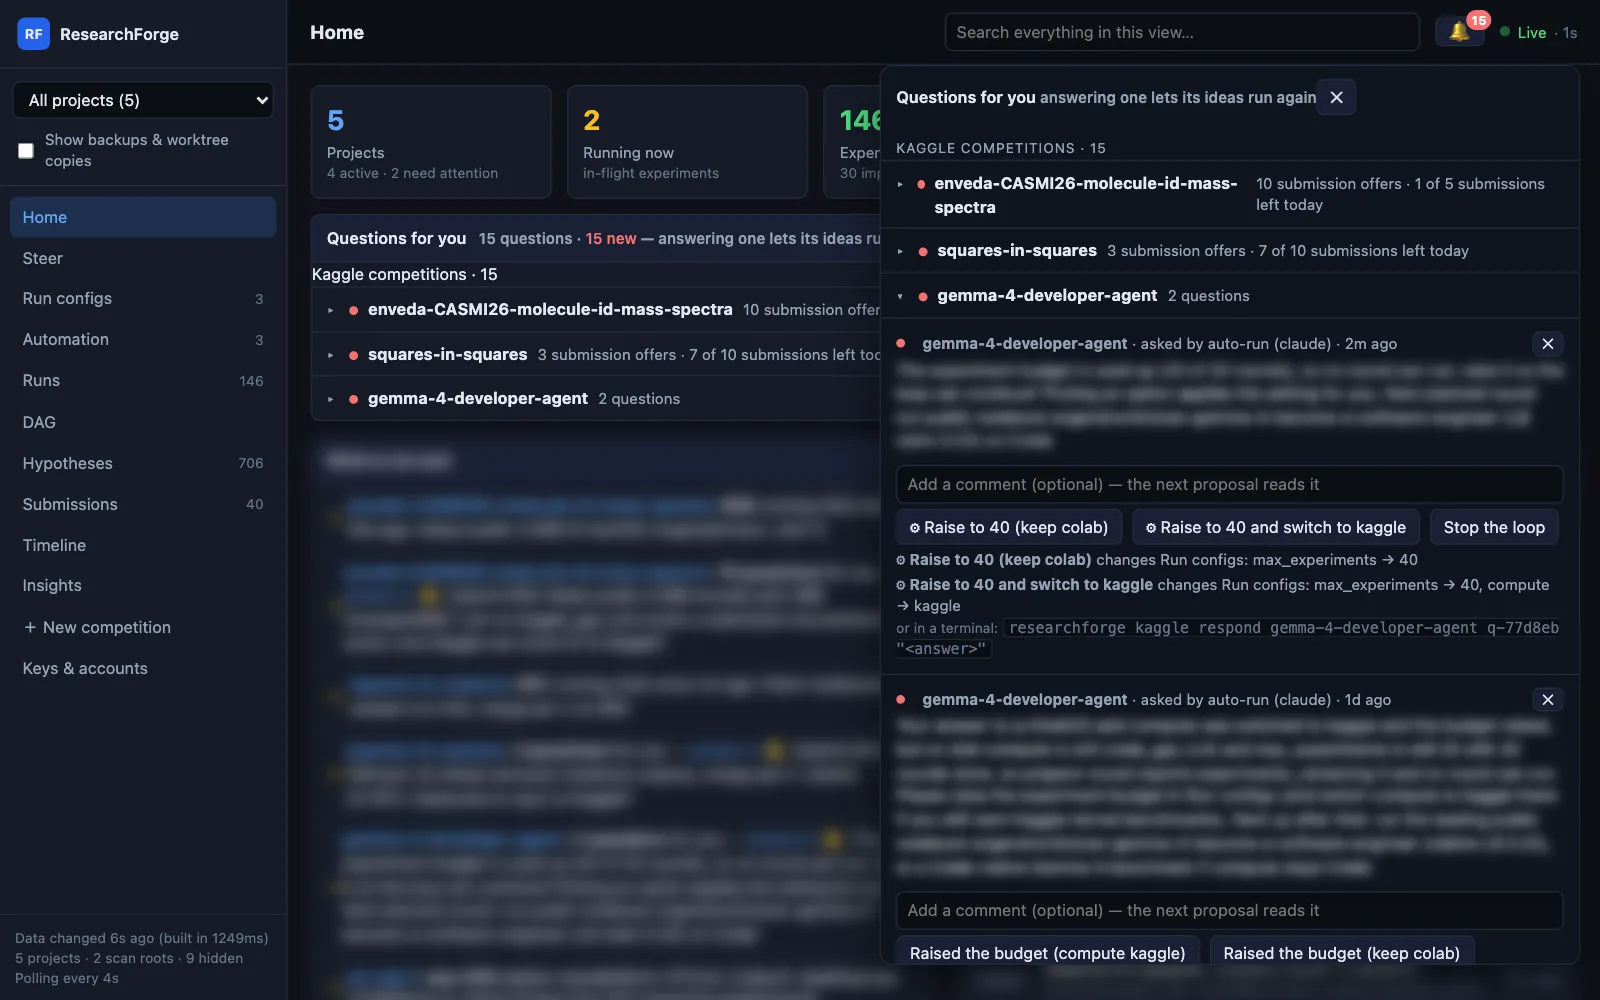
Where rounds run
Kaggle GPU · this machine · Google Colab (T4 to H100) · a competition GPU — used in real runs. Your SSH server · RunPod or Lambda — implemented and tested.
Compute in the docs →Who drives it
Claude Code on your subscription — used in real runs. The Cursor agent, or BYOK: your own Anthropic, Gemini or OpenAI key, or a local Ollama model — tested. One per project, switchable any time.
Drivers in the docs →Live dashboard
Every run, on one page, while it happens.
A local dashboard for every competition and repository on your machine: what to do next, the experiment tree, the idea pool, sensors, submissions and a timeline. Nothing leaves your machine.
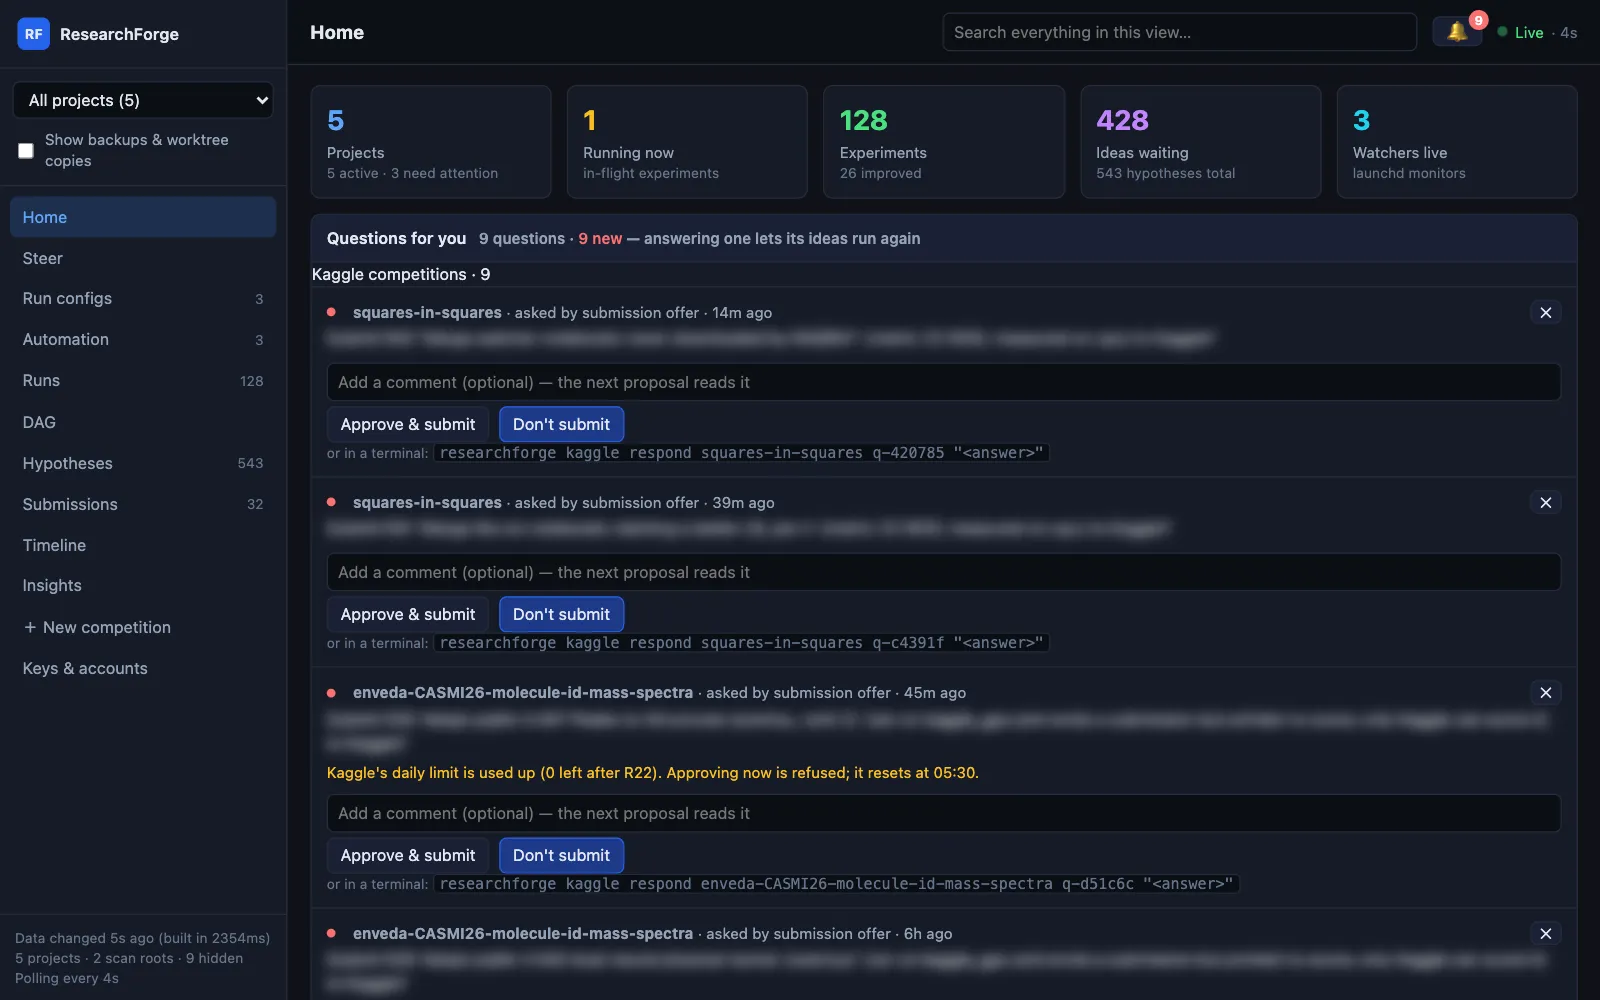
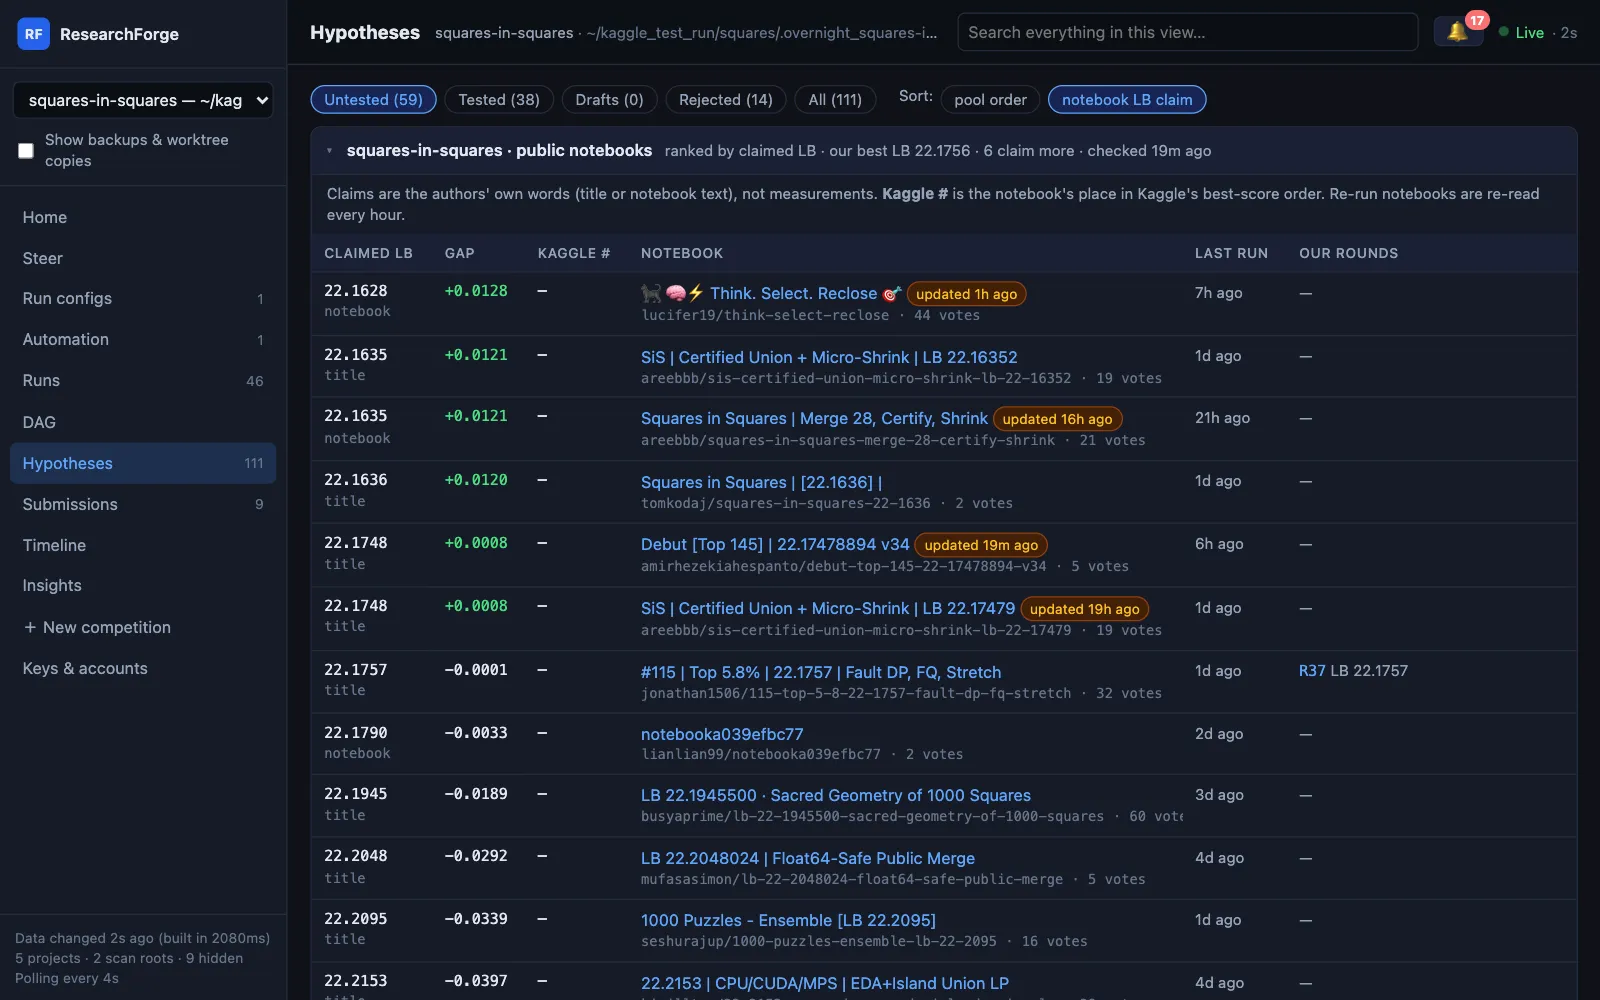
Try it on your next competition.
ResearchForge is built in the open by one small team. If it saves you a night of manual experiments, a GitHub star is how other Kagglers find it — and how you'll hear about new releases.
$ pip install researchforgeFor teams
When experimentation becomes maintenance.
Dependency upgrades, retraining on new data, model and prompt swaps — run as controlled jobs against a frozen baseline, with approvals, a full record and measured cost. Start with a 30-day pilot on one repository.
Common questions
Is ResearchForge autoresearch?+
It is an autoresearch-style loop, built independently. Andrej Karpathy’s autoresearch lets an agent edit one training script, run it for five minutes and keep the change only if validation loss improves. ResearchForge applies the same keep-or-revert idea to live Kaggle competitions and to any repository with a metric: a frozen baseline, isolated git worktrees, hard constraints, repeated validation, and every rejected idea kept with its reason.
How many experiments does it run overnight?+
As many as your compute and budget allow. On Squares in Squares, auto-run launched 40 of 46 rounds with no chat open; each round is a full run on the compute you pick, from about a minute to the round time limit you set.
Is ResearchForge an autonomous coding agent?+
No. Claude Code, Cursor or an API model proposes the ideas and writes the changes. ResearchForge is the protocol around them: it freezes the baseline, runs each change in isolation, measures it, rejects what fails and keeps the record.
Is Kaggle Overnight allowed by Kaggle’s rules?+
It automates what you would do by hand — run notebooks on your own account and keep notes. It never copies code from public kernels (it reads their titles for ideas) and never submits on its own. You are still responsible for each competition’s rules on external data and submissions.
Does my code or data leave my machine?+
The CLI runs locally and sends nothing to ResearchForge servers. With Kaggle compute, competition data stays on Kaggle. In API-key mode, the prompts ResearchForge builds — including relevant code — go to the AI provider you choose.
Do I need an API key?+
No. From Claude Code or Cursor, your editor’s AI does the thinking. With an Anthropic, Gemini or OpenAI key, or a free local model through Ollama, it runs headless without an editor. Either way the machine running the loop stays on.
How do I install it?+
pip install researchforge, then researchforge claude install --user for Claude Code (or the plugin: /plugin marketplace add forger-labs-hq/researchforge) or researchforge cursor install --user for Cursor. Then /overnight <url> or @overnight <url>.
What happens when an experiment fails?+
It stays in the record with the error or the constraint it violated. Nothing is hidden, and the loop will not retry the same idea.